NOW AVAILABLE | BUILT ON

Scality AI Inference Factory
Open-weight models on your own infrastructure, at a cost you set.
An open-code inference stack on Scality ADI (AI Data Infrastructure), validated, delivered and maintained by Scality. Keep your coding assistants, apps and agents, point them at one endpoint and keep every prompt inside your perimeter.
 Software license or fully managed service

 Cost, control and sovereignty
You control the model, the data and the cost.
Enterprises have found the AI workflows that pay off and now need them running at scale, every day. Three dependencies push the most critical ones onto infrastructure they own.


A budget that stays fixed.
A metered API bill grows with every token. On your own servers the budget is fixed, and the more your teams use it, the cheaper each token gets.


Data that stays yours.
Codebases, documents and tool outputs never leave your perimeter or your jurisdiction, and nobody outside your company can switch them off. The whole stack can run air-gapped.


The model you choose stays the model you run.
You choose from open-weight models Scality validates and delivers with the stack. Version, quantization and retirement change when you decide, not when a provider rebalances its fleet.
WHY A STORAGE COMPANY BUILT IT
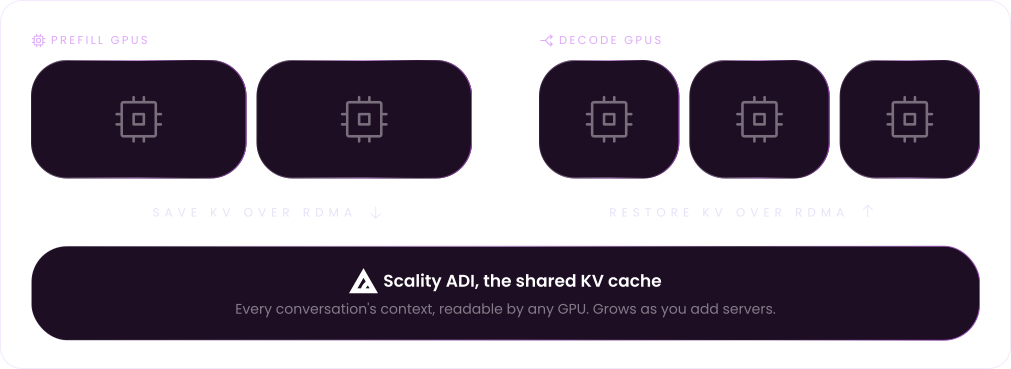
The hardest part of serving a model is its memory.
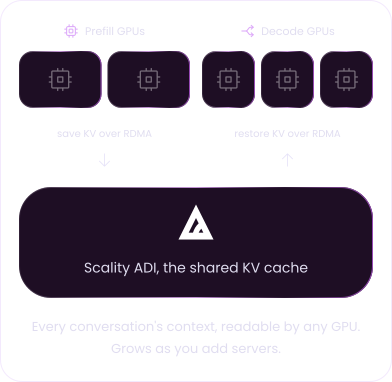
Every returning conversation is a choice between recomputing its context on the GPU and reading it back. That context, the KV cache, outgrows GPU memory fast. In our lab, one GLM-5.2 session with a 438,764-token context produced 189 GB of it. Ten thousand sessions like that would need about 1.9 PB, which makes it a storage tier rather than a cache.
MEASURED IN THE SCALITY LAB
Context restored in 166 ms, not recomputed in seconds.
WHAT YOU DEPLOY
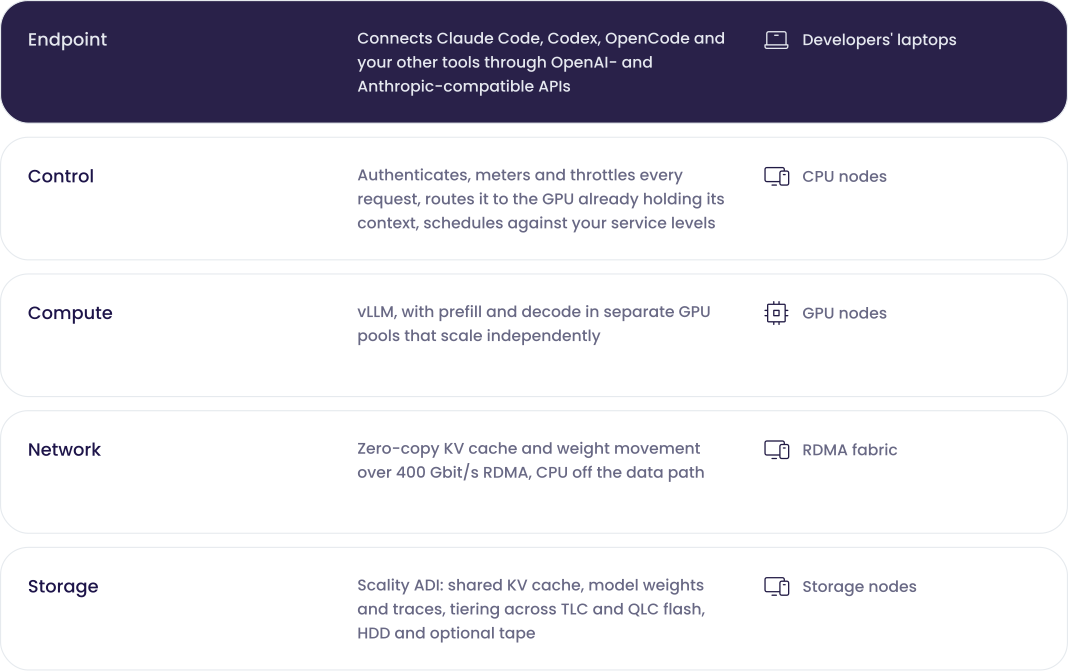
One endpoint over the whole serving stack.
Scality packages, validates, delivers and maintains every layer as models and serving engines change, on standard servers from Dell, HPE, Lenovo and Supermicro. Every software component ships as open code: you receive the source and can audit how inference state is stored and moved.
WORKS WITH YOUR TOOLS
Keep your harness. Choose a validated model.
Scality packages, validates, delivers and maintains every layer as models and serving engines change, on standard servers from Dell, HPE, Lenovo and Supermicro. Every software component ships as open code: you receive the source and can audit how inference state is stored and moved.

Harnesses, for example
and the other tools your developers use

APIs
and the other tools your developers use

Validated models



Standard servers

GO DEEPER
Read the story behind the launch.

Scality launches AI Inference Factory for enterprise on-premises AI
The announcement, availability and the three dependencies driving inference on premises.

Scality ADI
The AI Data Infrastructure underneath: one platform for AI, cyber resilience and sovereign control.

Don't rebuild the context, read it back
Why a storage company built an inference stack, and what the lab measured.

On-premises AI inference
The workloads it serves, the full lab results and where it fits.

Bring your traffic and a repository. We'll size it with you.